For AI Builders
Better models, faster.
You push the frontier. We build what the clean room can't produce: evals,
RL environments, reward models, and red-team batteries, drawn from live enterprise deployments - where models actually break.

New


You push the frontier. We build what the clean room can't produce: evals,
RL environments, reward models, and red-team batteries, drawn from live enterprise deployments - where models actually break.


Your model can do far more than it does today. The capability is already there. What it hasn't proven is that it holds up in the places that matter the regulated, integrated environments where enterprises actually run their business. Each one your model clears opens another use case, and enough of them add up to a new market.
We spend every week shipping models into production inside large, regulated enterprises. That's how we know what actually stands in the way: the document no one anticipated, the policy quietly violated, the tool call that loops, the long-horizon task that drifts. Public benchmarks miss all of it.
Yet it's what decides whether your model is cleared for real work.
We turn that into training signal you can own: evals modeled on real enterprise tasks, RL environments that mirror the systems your model will run inside, and red-team batteries calibrated to the failures we see in the field all built to drop into your next run. Every cycle, your model earns its way into more of the enterprise, and more of what it can do becomes something you can ship.

Post-training substrate.
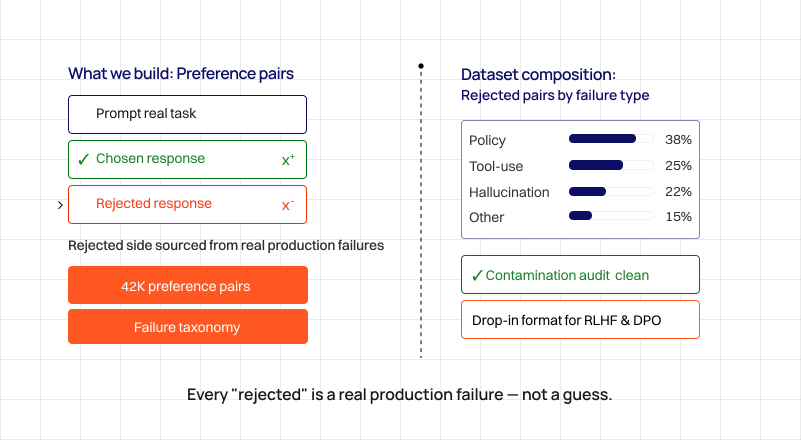
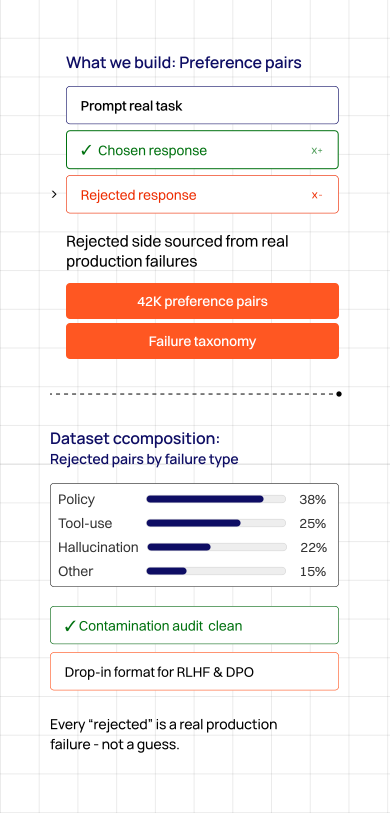
Everything your run consumes, built to your task SFT and preference datasets, reward models, and the rubrics and judges behind DPO, RLHF, and RLVR. We validate all of it against our eval substrate before it reaches your pipeline. Your team runs the training.
Domain dataset construction, contamination control, mixture optimization.
Reward/verifier design, scalable AI feedback, calibration.
Preference optimization, verifiable-reward design, training-loop instrumentation.
Rubric design, judge prompts, rejection-sampling pipelines.
The worlds your model trains in.
Agentic, high-fidelity environments that mirror the tools, systems, and long-horizon tasks your model will face in production, each instrumented for verifiable reward.
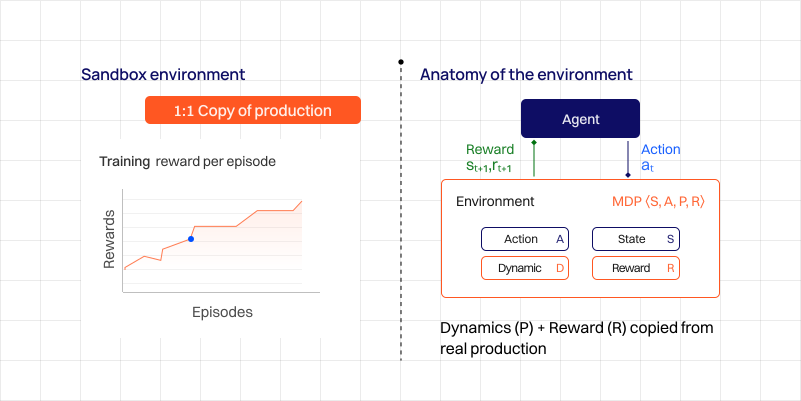
Sandboxed replicas of the enterprise tools and APIs your model has to operate.
Multi-step workflows with real state, drift, and recovery paths.
Programmatic success criteria that turn task outcomes into clean RL signal.
Environments built to a specific vertical's systems, data, and constraints.
Proof before you ship.
Task-realistic eval CI and adversarial batteries that surface what public benchmarks can't, calibrated to the failures we see in live deployments.
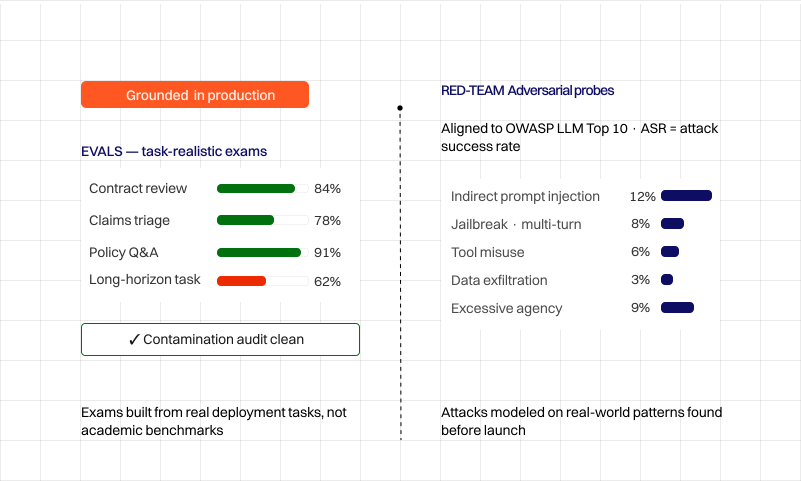
Measurement built on real enterprise work, not academic benchmarks.
Detection of train/test leakage and benchmark gaming.
Jailbreak, policy-violation, and tool-misuse batteries at scale.
Every checkpoint scored automatically before it reaches your release branch.
The inputs your behavior is made of.
Domain and synthetic datasets, engineered and quality-controlled for SFT and preference training, so what your model learns from is signal, not noise.
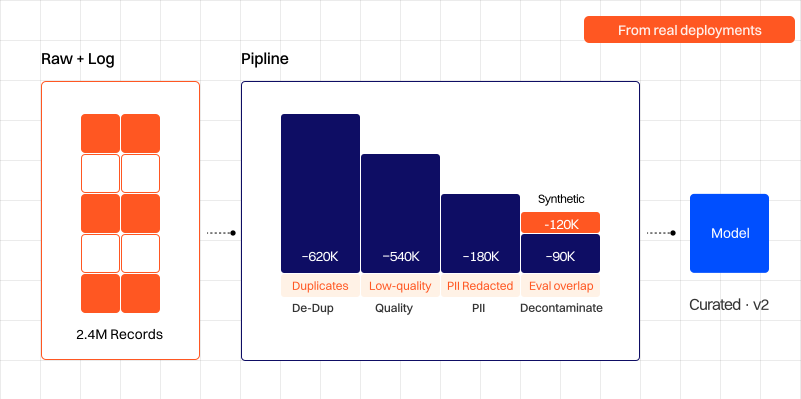
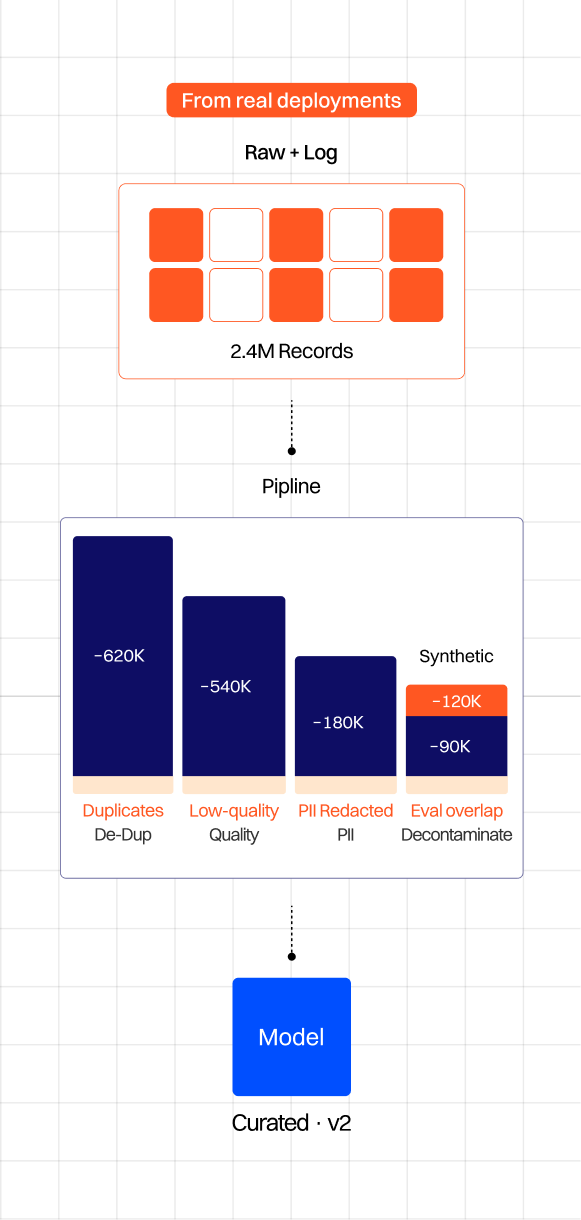
Model-assisted data generation with automated quality gating.
High-signal datasets drawn from real enterprise tasks.
Deduplication, leakage removal, mixture optimization.
Automated preference and rubric labeling, calibrated against human judgment.
No benchmark predicts the failures that keep a model out of production. They show up in the real world: a misread clause, a tool call that quietly loops, an edge case nobody wrote a test for. When it happens, our engineers are in it: working out what went wrong and building the training data your team needs to close the gap. Run after run, the model reaches further into the enterprise.


Your team runs it. We build what the run consumes: datasets, reward models, RL environments and evals, all validated before they reach your pipeline. If you want us to run the training as well, we can. It’s an option, not a requirement.
From our own deployments in finance, insurance, healthcare and the public sector. The data is anonymized, cleared for training use and contamination-controlled before delivery.
Benchmarks measure what’s easy to measure. Vendors sell what’s easy to collect. Our substrate is drawn from where models fail in production, such as a misread clause or a tool call that quietly loops, and is engineered to your task, not to a catalog.
That's the design constraint. Datasets arrive in your formats, environments are instrumented for verifiable reward, and eval CI scores every checkpoint before it reaches your release branch.
You do. Environments, datasets, and evals are engineered to your task and delivered as yours.